















































KI-Beratung Beta

Gutscheinbedingungen

Gültig bis 11.11.2026 | Gültig für Spielzeug, Filme, Musik, Software, Games, Geschenke & Trends, Schreibwaren, Hörbücher und Hörbuch-Downloads (außer Abo & Shelfies), gebrauchte Bücher, nicht preisgebundene Bücher und Kalender | Einlösbar unter thalia.de und in der Thalia App | Click & Collect nur mit Online-Zahlung (Paypal/Kreditkarte) vorab | Einzelne Artikel können ausgeschlossen sein | Nicht kombinierbar mit anderen Gutscheinen oder Preisaktionen | Nur einmal pro Einkauf einlösbar | Gutschein wird auf max. 500€ Bestellwert angerechnet | Keine Barauszahlung | Digitale Hörbücher nur für Android  | Nicht gültig für preisgebundene Artikel (aufgrund der Buchpreisbindung sind Gutscheine nicht auf Bücher, eBooks, Presse einlösbar), tolino eReader & Zubehör, Abonnements & Flatrates, Geschenkkarten, Versandkosten und Services

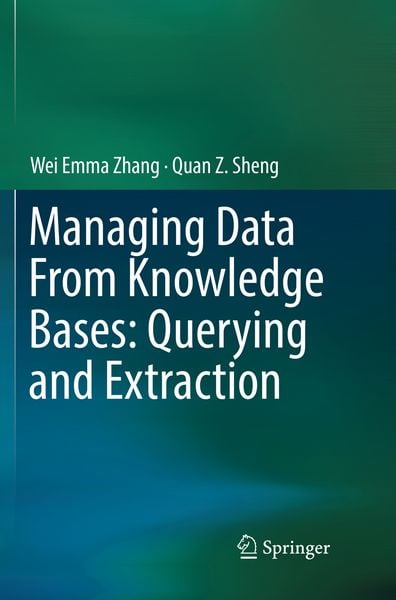
  • Produktbild: Managing Data From Knowledge Bases: Querying and Extraction
  • Produktbild: Managing Data From Knowledge Bases: Querying and Extraction

Managing Data From Knowledge Bases: Querying and Extraction

117,99 €

inkl. gesetzl. MwSt., Versandkostenfrei


Beschreibung

In this book, the authors first address the research issues by providing a motivating scenario, followed by the exploration of the principles and techniques of the challenging topics. Then they solve the raised research issues by developing a series of methodologies. More specifically, the authors study...

Beschreibung

In this book, the authors first address the research issues by providing a motivating scenario, followed by the exploration of the principles and techniques of the challenging topics. Then they solve the raised research issues by developing a series of methodologies. More specifically, the authors study the query optimization and tackle the query performance prediction for knowledge retrieval. They also handle unstructured data processing, data clustering for knowledge extraction. To optimize the queries issued through interfaces against knowledge bases, the authors propose a cache-based optimization layer between consumers and the querying interface to facilitate the querying and solve the latency issue. The cache depends on a novel learning method that considers the querying patterns from individual’s historical queries without having knowledge of the backing systems of the knowledge base. To predict the query performance for appropriate query scheduling, the authors examine the queries’ structural and syntactical features and apply multiple widely adopted prediction models. Their feature modelling approach eschews the knowledge requirement on both the querying languages and system.

To extract knowledge from unstructured Web sources, the authors examine two kinds of Web sources containing unstructured data: the source code from Web repositories and the posts in programming question-answering communities. They use natural language processing techniques to pre-process the source codes and obtain the natural language elements. Then they apply traditional knowledge extraction techniques to extract knowledge. For the data from programming question-answering communities, the authors make the attempt towards building programming knowledge base by starting with paraphrase identification problems and develop novel features to accurately identify duplicate posts. For domain specific knowledge extraction, the authors propose to use a clustering technique toseparate knowledge into different groups. They focus on developing a new clustering algorithm that uses manifold constraints in the optimization task and achieves fast and accurate performance.

For each model and approach presented in this dissertation, the authors have conducted extensive experiments to evaluate it using either public dataset or synthetic data they generated.

Produktdetails

Einband

Taschenbuch

Erscheinungsdatum

19.01.2019

Abbildungen

XIII, 139 p. 41 illus., 32 illus. in color.

Verlag Springer

Produktdetails

Einband

Taschenbuch

Erscheinungsdatum

19.01.2019

Abbildungen

XIII, 139 p. 41 illus., 32 illus. in color.

Verlag Springer
Seitenzahl

139

Maße (L/B/H)

23,5/15,5/0,9 cm

Gewicht

248 g

Sprache

Englisch

ISBN

978-3-030-06940-7

Herstelleradresse

Springer-Verlag KG
Sachsenplatz 4-6
1201 Wien
AT

Email: ProductSafety@springernature.com

Ein neues Kapitel für Ihre Bücher

Ein neues Kapitel für Ihre Bücher

Schenken Sie Ihren alten Schätzen ein zweites Leben und erhalten Sie dafür eine Thalia Geschenkkarte.

Jetzt verkaufen
Jetzt verkaufen

Noch keine Bewertungen vorhanden

Verfassen Sie die erste Bewertung zu diesem Artikel

Helfen Sie anderen Kundinnen und Kunden durch Ihre Meinung.

Kundinnen und Kunden meinen

Bewertungen (0)

  • Produktbild: Managing Data From Knowledge Bases: Querying and Extraction
  • Produktbild: Managing Data From Knowledge Bases: Querying and Extraction
  • 1 Introduction.- 2 Cache Based Optimization for Querying Curated Knowledge Bases.- 3 Query Performance Prediction on Knowledge Base.- 4 An Efficient Knowledge Clustering Algorithm.- 5 Knowledge Extraction from Unstructured Data on the Web.- 6 Building Knowledge Bases from Unstructured Data on the Web.- 7 Conclusion.